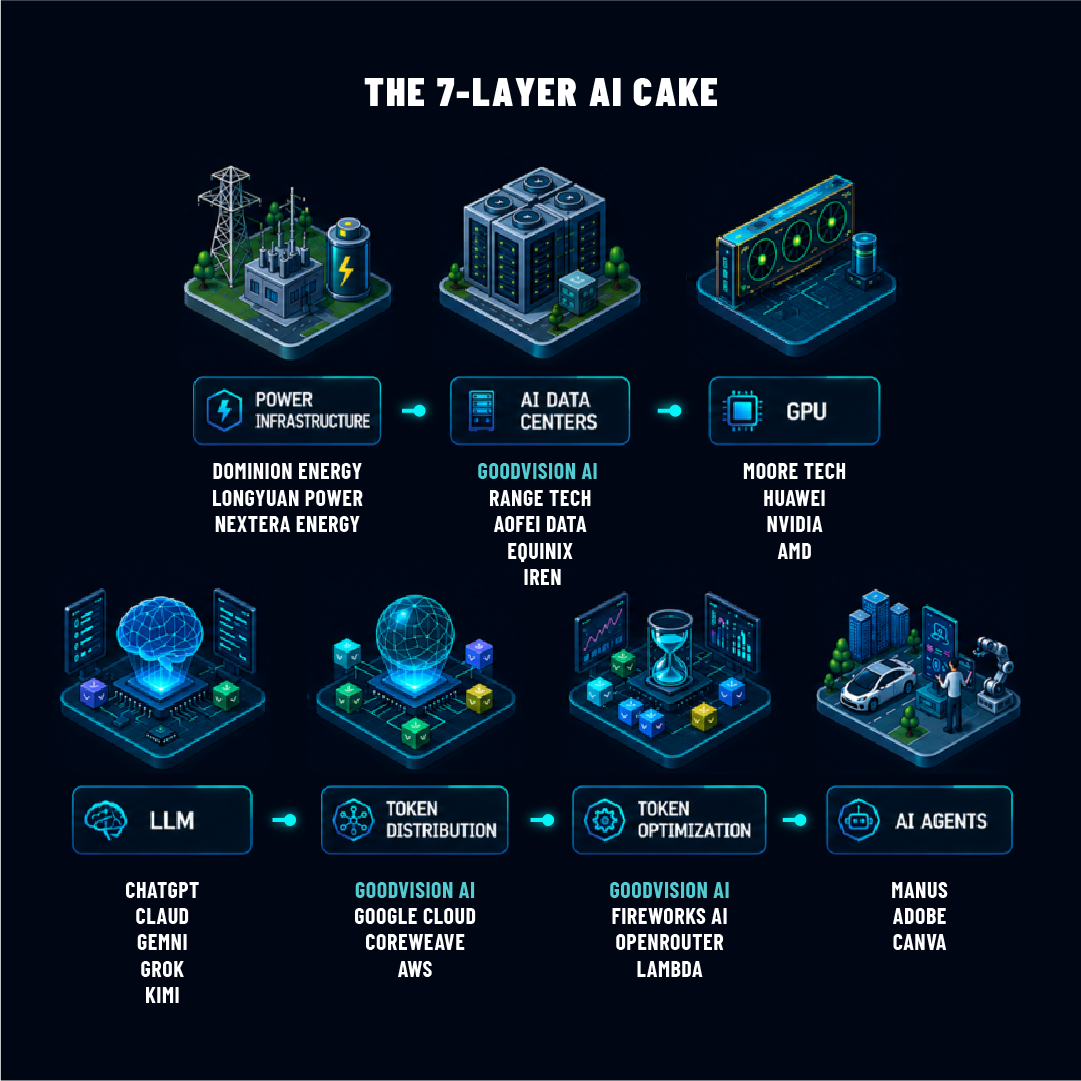
Model selection is merely the starting point for an AI request.
Consider an AI agent processing an insurance claim: it analyzes photos of a damaged bumper, retrieves the relevant insurance policy, compares repair estimates against local market rates, generates a summary, and then hands the file off to a human claims adjuster.
In this scenario, the company might trigger 40 or more calls to an AI model to complete a single task.
Each task carries its own specific requirements. Reading a scanned form is straightforward—it can be handled by a smaller, less powerful model at a cost of just a few cents. Detecting potential fraud in a claim, however, requires a larger, slower model; furthermore, if the documentation includes medical records, there may be legal restrictions preventing that data from crossing national borders.
For the past three years, the primary focus for enterprises has been which AI model to choose. Now, the focus has shifted toward broader deployment challenges: which model should handle each specific request, where should it run, and is there sufficient capacity to manage the workload?
This shift is becoming evident in corporate budgets. According to Gartner, even as the cost for service providers to run AI inference declines, the number of tokens consumed per task by an AI agent can be 5 to 30 times higher than that of a standard chatbot interaction. EY (Ernst & Young) provides further insight: a customer service interaction that cost approximately $0.04 in 2023 could rise to roughly $1.20 by 2026 if handled by an “orchestrated agent”—a system that integrates various tools, multi-step reasoning, and sub-agents.
The balance of AI-related computing costs is also shifting. Gartner forecasts that global spending on inference will surpass spending on model training this year—$23.3 billion versus $19 billion, respectively. McKinsey projects that demand for inference will grow at a compound annual growth rate (CAGR) of 35% through 2030, at which point it will become the dominant AI workload in data centers.
Three issues—previously the domain of separate teams—now converge: which model is best suited for the job, where the computing resources to run it are located, and who will be responsible for maintaining it once it is deployed. “Companies spend months selecting a model, only to discover that the selection process is the easiest part,” says David Wang, founder and CEO of GoodVision AI. “In a production environment, a single application makes thousands of micro-decisions every second—regarding which model to use, what environment to run it in, and how to manage costs. These decisions determine whether an AI pilot project survives its first year.”
Founded in California in 2019, GoodVision AI provides and manages cloud capacity for enterprises in the gaming, video, and cross-border e-commerce sectors. Since March of this year, the company has also offered inference services—billed on a usage basis—powered by an intelligent routing engine that determines how each request should be handled. A third business unit, “AI Factory,” focuses on deploying inference compute resources at compact sites located closer to end users. Before founding GoodVision AI, Wang spent over 25 years working at IBM, Amazon Web Services (AWS), and Intel.
Every request is a placement decision.
Few companies today rely on just a single model. Research commissioned by Vultr and conducted by S&P Global Market Intelligence found that enterprises at the forefront of AI adoption run an average of 175 models in production—a figure expected to reach 200 within a year.
Relying on a single, default model forces a compromise for every request. Using the largest, most powerful model for tasks that could be handled by a smaller, more efficient one is unnecessarily costly; for instance, Anthropic has priced its Claude Haiku 4.5 model at one-third the cost of Claude Sonnet 4.5, while reporting comparable coding performance in certain benchmarks. Conversely, routing all requests to a smaller model would cause more complex tasks to fail. Furthermore, sending regulated data to a public endpoint introduces compliance risks.
Engineering teams have begun building their own solutions. In an August post on its engineering blog, Uber reported that updating the models used in its automated code-review system improved quality scores while simultaneously reducing the cost per pull request. This change was part of a broader initiative that lowered the cost per 1,000 model requests by approximately 34% from its peak. Sword Health built an internal agent to sit between its tools and its model providers; the company attributes 94% of its cost savings to routing tasks toward more affordable, self-hosted models.
Major cloud platforms have since productized this capability. In April 2025, AWS officially launched “Bedrock Intelligent Prompt Routing,” claiming it can reduce costs by up to 30%. At its Build 2025 conference, Microsoft introduced the “Foundry Model Router,” which selects a specific model for each individual request. Google Cloud added model routing functionality to its API Gateway in August 2026. While these solutions address the question of which model to run, they do not determine the geographic region where a request should be processed, nor can they decide whether a request should be executed on hardware located outside of a hyperscaler’s infrastructure.
GoodVision AI’s intelligent routing engine evaluates each request based on four criteria: complexity, latency requirements, cost, and data sensitivity. It then selects the appropriate model and environment—utilizing public cloud resources for general tasks, while routing sensitive or latency-critical workloads to dedicated or on-premises computing resources—all powered by NVIDIA’s inference software. Wang describes this approach as “selecting the right model for the right task.” The platform entered a limited preview for select enterprise clients in February 2026, with the company beginning to sell inference services the following month; a broader, general release remains in the planning stages.
Two deployment cases illustrate the platform’s broad utility. A game studio, which had designed an in-game agent system but lacked the necessary computational resources to focus on gameplay development, opted to build the system on this platform; GoodVision AI reported a reduction in token costs of up to 35% and a decrease in development workload of up to 60%. Another client—a biotechnology firm—faced bottlenecks in its customer data import process due to manual operations; by automating these steps, the company achieved a reduction in token costs of up to 40% and a 70% decrease in manual labor. A study commissioned by the company from Frost & Sullivan modeled a hybrid architecture that keeps sensitive, high-frequency tasks on-premises; compared to sending all data to a single public API, this approach requires approximately 70% fewer tokens.
“Every request comes with three constraints: cost, response speed, and data flow,” Wang explains. “While an individual might be able to balance these factors for a single request, no one can manage that for a million requests a day.”
Routing can only function if the underlying computational resources are available.
Data center siting is constrained by physical limitations. The International Energy Agency (IEA) projects that electricity consumption by data centers will more than double by 2030, reaching approximately 945 terawatt-hours—slightly more than Japan’s current total annual electricity consumption. The Electric Power Research Institute (EPRI) forecasts that by 2030, data center electricity consumption in the United States will range between 383 and 793 terawatt-hours—two to four times the 2024 levels.
The integration of new capacity is proceeding slowly. A January report from JLL indicates that the average wait time for grid connection in major data center markets now exceeds four years. According to the IEA, wait times across the European Union vary from two to ten years, with delays reaching seven to ten years in key hubs such as Frankfurt, London, Amsterdam, Paris, and Dublin.
Governments around the world are independently investing in the development of their own artificial intelligence capabilities. South Korea is building a national AI computing center with a budget of up to 2 trillion KRW; meanwhile, in July of this year, the European Commission launched a tender to develop up to seven “AI factories”—supercomputing facilities supported by as much as 10 billion EUR in public funding.
Routers can determine whether a request should be routed to, say, Fukushima or Dallas—rather than to a hyperscale data center—but such a decision is meaningless if there is no actual capacity available at the destination to process the request.
GoodVision AI has signed three non-binding agreements to establish “AI Factories”—specialized data centers—in Fukushima (Japan), Texas (USA), and Gimpo (South Korea). Each facility features a compact, high-density, liquid-cooled design, with an initial capacity ranging from 1.5 MW to 5 MW, scalable based on demand. These data centers are positioned close to the end users and within the same legal jurisdictions where the data resides, offering an alternative to hyperscale data centers. Initial deployments are planned for this year, and the company states that each facility can be operational within 30 days of equipment installation. Currently, the company’s routing platform relies on capacity purchased from major cloud service providers—a dependency that also imposes capacity constraints on most of its clients.
“People might ask, why would a routing company build computing sites?” says Wang. “Routing is essentially a decision-making process. If there isn’t sufficient capacity where a task needs to be executed, that decision becomes meaningless. Both aspects must be addressed in tandem.”
And, of course, someone has to operate it.
A third challenge is that AI applications in production environments are constantly evolving, requiring ongoing management. Since these changes often emerge only after an application has gone live, they are frequently overlooked. For instance, a vendor might deprecate a specific model version upon which an application relies, or prompts optimized for an older version might perform differently on a newer one. Pricing structures and rate limits can shift, altering the economic viability of certain features. A product might suddenly gain traction on a Tuesday, causing traffic to surge tenfold. Or, a new contract might stipulate that customer data cannot be processed outside the European Union, necessitating the migration of workloads.
This operational responsibility falls to the company’s existing cloud account operations team—the very team from which GoodVision AI originated. The cloud team handles procurement, migration, performance tuning, and day-to-day operations across various major cloud service providers. According to the company, this work has helped clients reduce their actual cloud bills—as opposed to theoretical cost savings—by 30% to 50% compared to standard public cloud pricing. Among GoodVision AI’s three business lines, the cloud segment is the least innovative; however, for most enterprise buyers, it is the deciding factor in whether the other two business lines can ultimately be deployed into production.
“Inference is not a project with a fixed deadline,” Wang says. “It runs every single day and evolves every month. Most teams underestimate this.”
Turning Inference Demand into Revenue
Cloud services remain the foundation of GoodVision AI’s business. According to the S-4 filing submitted to the U.S. Securities and Exchange Commission (SEC), the company’s revenue was approximately $3.6 million for fiscal year 2024 and $7.7 million for fiscal year 2025, with revenue reaching approximately $24 million for the nine-month period ending June 30, 2026.
The next phase of growth depends, in part, on bringing “AI factories” online. Projections disclosed by management in the S-4 filing indicate a deployed capacity of approximately 17.5 megawatts for these AI factories by fiscal year 2027, growing to roughly 40 megawatts by fiscal year 2028. Based on these capacity projections, management anticipates that revenue from AI factory computing services will reach approximately $64 million in fiscal year 2027 and $224 million in fiscal year 2028. These forecasts are contingent upon site development, equipment procurement, financing, and customer commitments.
It is often assumed that growth of this magnitude implies selling a higher volume of tokens. Wang, however, takes a different view:
“Customers are buying the end result of a business task, not a quantity of tokens.” By eliminating unnecessary calls and retries, more optimized routing can reduce token consumption while simultaneously increasing the value delivered.
The S-4 filing regarding the proposed merger with Calisa became effective on September 11, with a shareholder vote scheduled for October 8. The completion date for the transaction has not yet been determined. Mr. Wang stated that the proceeds will primarily be used to build new AI infrastructure, further develop intelligent routing engines, and expand sales and R&D teams.
The advantage lies in the layer beneath the models.
Any company can access the same models via the same APIs. What is truly difficult to replicate is everything that happens underneath: determining where each task should be executed, ensuring sufficient resources are available to run it, and maintaining a stable operational framework—all while models, pricing, and rules are constantly shifting. This is precisely where the advantage in enterprise-grade AI resides.
Many challenges remain unresolved. Evaluating whether a routing decision is correct is still difficult, as quality is harder to quantify than cost. The growth in computing capacity is failing to keep pace with rising demand, and operating across multiple vendors and locations introduces added complexity—complexity that ultimately comes at a cost.
“Anyone can purchase these models,” says Wang. “The pilot projects that actually survive are those that make the right decisions about the next steps: where to execute a task, what the cost of doing so will be, and whether there is sufficient capacity. This is the ‘reasoning layer’ that powers AI operations.”